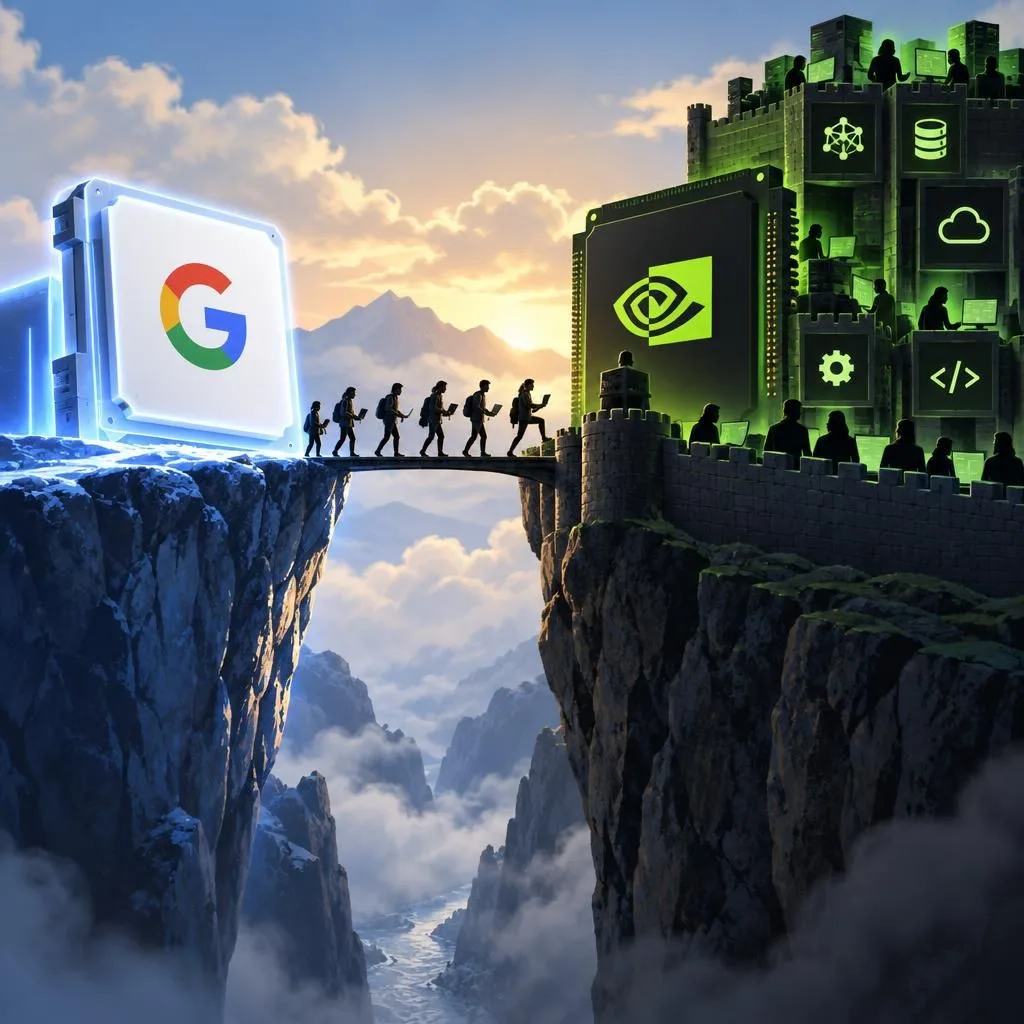
As artificial intelligence models continue to expand in scale and complexity, the debate over computing hardware has intensified. At the center of this battle is Google's Tensor Processing Unit (TPU) and Nvidia's dominant Graphics Processing Units (GPUs). Yet the true contest is rarely just about raw silicon specifications. Instead, the central question is whether Google's hardware and its supporting software stack can overcome the immense competitive moat established by Nvidia's proprietary computing platform, CUDA.
To evaluate whether Google can win, it is essential to recognize that comparing TPUs directly to CUDA compares an application-specific integrated circuit (ASIC) with a software development platform. Nvidia’s CUDA (Compute Unified Device Architecture) has spent nearly two decades evolving into the default standard for GPU-accelerated computing. It provides low-level primitive libraries, profiling tools, and direct kernel optimizations that millions of engineers rely on daily.
In contrast, Google's TPU is a domain-specific accelerator designed primarily around matrix multiplication (using systolic array architectures). Its software interface relies heavily on intermediate compilers such as XLA (Accelerated Linear Algebra) and higher-level frameworks like JAX and TensorFlow, rather than offering direct, imperative kernel hacking in the way CUDA does.
Why CUDA’s Moat Remains Resilient
Nvidia's software dominance is sustained by powerful network effects and deep enterprise switching costs:
Developer Mindshare and Education: For over fifteen years, computer science curricula, doctoral research, and open-source AI projects have been built natively on CUDA. Most published cutting-edge AI research provides code repositories that assume an Nvidia environment.
The PyTorch Ecosystem: PyTorch has become the dominant deep learning framework for researchers and enterprise practitioners. While PyTorch can target TPUs via PyTorch/XLA, its native performance, debugging ergonomics, and custom operator extensions are overwhelmingly refined on Nvidia GPUs.
Vendor Neutrality Across Clouds: Nvidia GPUs can be deployed anywhere—on Amazon Web Services, Microsoft Azure, Google Cloud, Oracle Cloud, or on-premises data centers. TPUs, however, remain largely tied to Google Cloud Platform, creating strategic lock-in concerns for enterprises wary of single-provider dependency.
Where TPUs Hold the Advantage
Despite CUDA's entrenched position, Google's TPU initiative is far from an underdog in pure technical capability. Inside Google's own production environment, TPUs power massive workloads, including Search, YouTube recommendations, and frontier models like Gemini.
Key factors that allow TPUs to compete include:
Co-designed Interconnects (Optical Circuit Switches): TPU clusters (Pods) benefit from custom networking architectures that deliver exceptional scaling efficiency, allowing massive supercomputing clusters to train foundation models with minimal networking bottlenecks.
Cost and Energy Efficiency: Because TPUs are purpose-built for tensor arithmetic and lack legacy graphics pipelines, they often deliver superior price-to-performance and energy efficiency per floating-point operation compared to general-purpose GPUs.
The Rise of OpenXLA and JAX: JAX has gained tremendous popularity among machine learning researchers for high-performance numerical computing. Together with OpenXLA—an open-source consortium aiming to make compilation hardware-agnostic—the industry is actively working to decouple model architectures from proprietary CUDA kernels.
The Verdict: Replacement or Parallel Coexistence?
Can Google's TPU "defeat" CUDA in enterprise computing? In the near to medium term, an outright replacement across the broader enterprise market is improbable. CUDA's ubiquity, toolchain matureness, and hardware availability across all major clouds give Nvidia an enduring competitive shield.
The competition between TPUs and CUDA is not a zero-sum hardware clash; it is an economic tug-of-war between specialized cloud-native scale and universal developer mobility.
Rather than killing CUDA, Google's TPU strategy serves a different, highly successful purpose: it insulates Alphabet from Nvidia's pricing power, guarantees internal computational sovereignty, and provides cost-conscious cloud customers a credible alternative for large-scale training. As compiler layers like Triton and OpenXLA mature, the friction of moving between CUDA and custom ASICs will shrink, steadily loosening—though not entirely breaking—Nvidia's legendary software grip.